Enterprise Capacity Planning Framework
This project presents a structured Enterprise Infrastructure Capacity Assessment Framework for evaluating the scalability of production environments using observed infrastructure metrics and workload analysis. The assessment identifies resource bottlenecks, forecasts growth capacity, and provides infrastructure scaling recommendations in scenarios where comprehensive end-to-end load testing is impractical. The framework supports data-driven capacity planning while documenting assumptions, risks, and future scaling considerations.
Azure · AWS
1.Overview
Modern enterprise applications are expected to scale continuously while maintaining high availability and consistent performance. In production environments, however, conducting comprehensive end-to-end load testing is often impractical due to operational risks, infrastructure limitations, cost, or customer constraints. As a result, infrastructure scaling decisions must frequently be made using observed production behavior rather than synthetic workloads.
This project presents a structured methodology for assessing the capacity of a live production environment by analyzing infrastructure utilization across critical application components, including compute, databases, caching, API gateways, ingress, and container orchestration platforms. The objective is to determine current resource headroom, identify potential bottlenecks, estimate future growth capacity, and provide actionable scaling recommendations based on real operational data.
The assessment follows a data-driven approach that combines historical production metrics, application deployment topology, autoscaling configurations, Kubernetes workload analysis, and infrastructure service limits to evaluate the scalability of each component individually before assessing the platform as a whole. Rather than assuming infrastructure components scale uniformly, the framework identifies the limiting resource for each service and documents the risks associated with theoretical capacity estimation, recognizing that application performance is influenced by workload characteristics, resource contention, inter-service dependencies, and downstream system behavior.
The outcome of the assessment is a comprehensive capacity planning report containing infrastructure utilization summaries, bottleneck analysis, growth forecasts, scaling recommendations, deployment considerations, and identified operational risks. This enables engineering teams to make informed infrastructure planning decisions while minimizing unnecessary resource allocation and reducing the likelihood of capacity-related production incidents.
2.Gallery
Pinch or scroll to zoom (50%–800%) · drag when zoomed in
3.Architecture
flowchart TD

%% ==========================================================
%% ENTERPRISE CAPACITY ASSESSMENT FRAMEWORK
%% ==========================================================

A([Capacity Assessment Initiation])

A --> B[Collect Environment Information]

B --> B1[Infrastructure Inventory]
B --> B2[Application Architecture]
B --> B3[Deployment Topology]
B --> B4[Business Growth Assumptions]
B --> B5[High Availability Requirements]

B1 --> C
B2 --> C
B3 --> C
B4 --> C
B5 --> C

C[Collect Production Metrics]

C --> C1[Azure Monitor]
C --> C2[Application Insights]
C --> C3[Prometheus / Grafana]
C --> C4[Azure Portal]
C --> C5[Kubernetes Metrics]
C --> C6[Historical Trend Data]

C1 --> D
C2 --> D
C3 --> D
C4 --> D
C5 --> D
C6 --> D

%% ==========================================================

D[Component-wise Capacity Assessment]

D --> AKS
D --> APP
D --> MYSQL
D --> REDIS
D --> APIM
D --> AGW
D --> STORAGE
D --> NETWORK

%% ==========================================================

subgraph Kubernetes

AKS[AKS Cluster]

AKS --> AKS1[Node Utilization]

AKS --> AKS2[CPU Headroom]

AKS --> AKS3[Memory Headroom]

AKS --> AKS4[Pod Density]

AKS --> AKS5[Autoscaling Limits]

end

%% ==========================================================

subgraph Application

APP[Application Pods]

APP --> APP1[Replica Count]

APP --> APP2[CPU Requests]

APP --> APP3[CPU Limits]

APP --> APP4[Memory Requests]

APP --> APP5[Memory Limits]

APP --> APP6[HPA Configuration]

end

%% ==========================================================

subgraph Database

MYSQL[Azure MySQL]

MYSQL --> M1[CPU]

MYSQL --> M2[Memory]

MYSQL --> M3[Connections]

MYSQL --> M4[Storage Growth]

MYSQL --> M5[IOPS]

MYSQL --> M6[Backup Growth]

end

%% ==========================================================

subgraph Cache

REDIS[Azure Redis]

REDIS --> R1[Memory Utilization]

REDIS --> R2[Cache Hit Ratio]

REDIS --> R3[Eviction Rate]

REDIS --> R4[Throughput]

end

%% ==========================================================

subgraph Gateway

AGW[Application Gateway]

AGW --> G1[Throughput]

AGW --> G2[Listeners]

AGW --> G3[Backend Health]

AGW --> G4[WAF Capacity]

end

%% ==========================================================

subgraph API

APIM[API Management]

APIM --> A1[Request Volume]

APIM --> A2[Latency]

APIM --> A3[SKU Limits]

APIM --> A4[Backend Connectivity]

end

%% ==========================================================

subgraph Storage

STORAGE[Persistent Storage]

STORAGE --> S1[Disk Capacity]

STORAGE --> S2[Storage Growth]

STORAGE --> S3[IOPS]

STORAGE --> S4[Throughput]

STORAGE --> S5[Expansion Window]

end

%% ==========================================================

subgraph Networking

NETWORK[Infrastructure Dependencies]

NETWORK --> N1[Ingress]

NETWORK --> N2[Egress]

NETWORK --> N3[Load Distribution]

NETWORK --> N4[Inter-service Dependencies]

end

%% ==========================================================

AKS --> CALC
APP --> CALC
MYSQL --> CALC
REDIS --> CALC
AGW --> CALC
APIM --> CALC
STORAGE --> CALC
NETWORK --> CALC

%% ==========================================================

CALC[Capacity Calculation Engine]

CALC --> F1

F1["Headroom % = (Available / Total) × 100"]

CALC --> F2

F2["Projected Utilization = Current × Growth Factor"]

CALC --> F3

F3["Monthly Growth = Δ Resource / Observation Period"]

CALC --> F4

F4["Time to Saturation = Remaining Capacity / Growth Rate"]

CALC --> F5

F5["Infrastructure Limit = Lowest Component Capacity"]

%% ==========================================================

F1 --> DECISION
F2 --> DECISION
F3 --> DECISION
F4 --> DECISION
F5 --> DECISION

%% ==========================================================

DECISION{Component Healthy?}

DECISION -- Yes --> OK

OK[No Immediate Action]

DECISION -- No --> BOTTLENECK

BOTTLENECK[Identify Bottleneck]

BOTTLENECK --> TYPE

TYPE{Scaling Strategy}

TYPE -->|Horizontal| SCALEOUT

TYPE -->|Vertical| SCALEUP

TYPE -->|Neither| REDESIGN

SCALEOUT[Increase Replicas / Nodes]

SCALEUP[Increase SKU / Compute]

REDESIGN[Architectural Recommendation]

%% ==========================================================

OK --> REPORT

SCALEOUT --> REPORT

SCALEUP --> REPORT

REDESIGN --> REPORT

%% ==========================================================

REPORT[Capacity Assessment Report]

REPORT --> REP1[Infrastructure Utilization]

REPORT --> REP2[Bottleneck Analysis]

REPORT --> REP3[Growth Forecast]

REPORT --> REP4[Risk Register]

REPORT --> REP5[Engineering Assumptions]

REPORT --> REP6[Scaling Recommendations]

REPORT --> REP7[Confidence Level]

%% ==========================================================

REP7 --> REVIEW

REVIEW{Load Testing Available?}

REVIEW -- Yes --> VALIDATE

VALIDATE[Validate Forecast Using Performance Testing]

REVIEW -- No --> MONITOR

MONITOR[Continue Production Monitoring]

VALIDATE --> END

MONITOR --> END

END([Capacity Planning Complete])4.Implementation
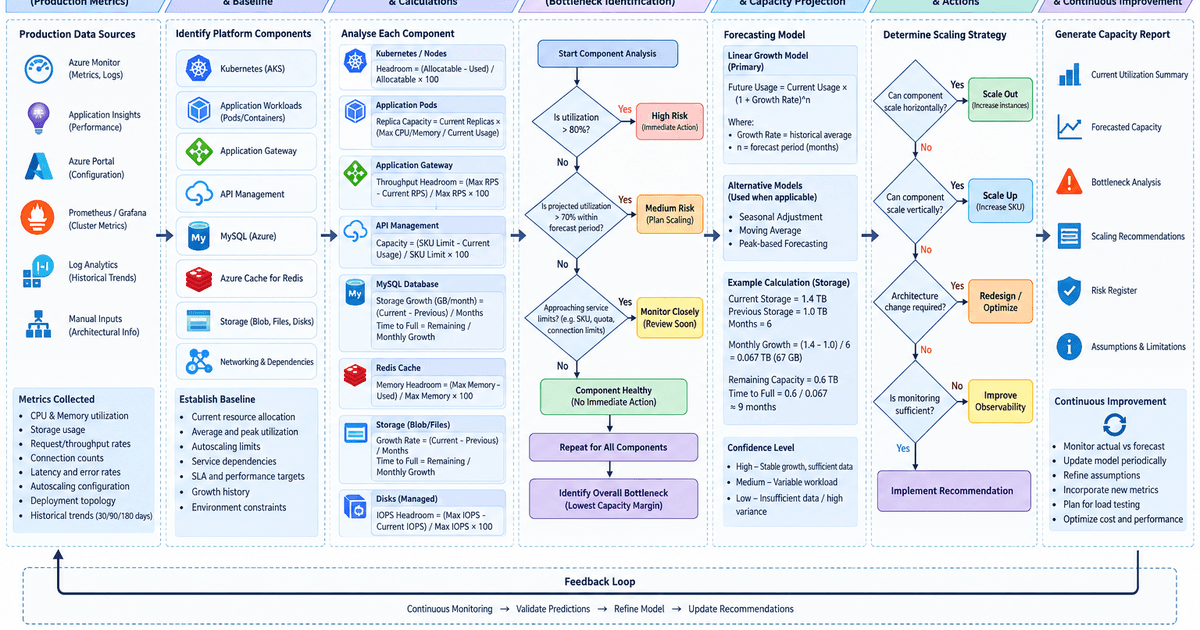
The assessment follows a component-driven analytical methodology where each infrastructure service is evaluated independently before deriving the overall platform capacity. Rather than treating the deployment as a single scalable system, every critical infrastructure component is assessed to determine its individual resource headroom, scaling characteristics, service limitations, and projected saturation point. The overall platform capacity is then constrained by the first component expected to reach its operational limit.
The assessment begins by establishing a production baseline using observed infrastructure metrics collected over a representative operating period. For each service, average utilization, peak utilization, autoscaling configuration, provisioned resources, and deployment topology are documented to establish the current operating state.
The following infrastructure components are evaluated independently (subsets of the complete list):Azure Kubernetes Service: Node utilization, allocatable resources, pod density, autoscaling limits
Application Workloads: CPU & Memory requests/limits, replica distribution, HPA behaviour
Azure Database for MySQL: CPU utilization, memory consumption, storage growth, connection capacity, IOPS
Azure Cache for Redis: Memory utilization, cache hit ratio, throughput, eviction risk
Azure API Management: Throughput, request capacity, SKU limits, backend connectivity
Azure Application Gateway: Request volume, throughput, listener capacity, WAF overhead
Azure Storage Services: Capacity growth, transaction rates, redundancy considerations
Persistent Storage: Disk utilization, IOPS, throughput, storage expansion requirements
Rather than extrapolating platform capacity directly, each service is analysed using its own operational characteristics. Available headroom is calculated from observed production utilization, after which theoretical scaling limits are estimated using documented assumptions regarding workload growth, infrastructure behaviour, and application architecture.
A simplified example of the analytical approach is shown below.
Current CPU Utilization = 38%
Available Capacity = 100 - 38 = 62%
Expected Growth = 20%
Projected Utilization = Current Utilization × Growth Factor
= 38 × 1.20
= 45.6%
Similarly, storage growth is estimated using historical consumption trends.
Average Monthly Growth = (Current Storage − Previous Storage) / Months Observed
Projected Full Capacity = Remaining Capacity / Average Monthly Growth
Each infrastructure component is then classified according to its projected operational headroom, identifying services that are expected to become limiting factors before others. The overall platform capacity is determined by the component with the lowest remaining scalability margin rather than by aggregate infrastructure utilization.
The final report consolidates these independent assessments into an enterprise capacity planning document containing projected infrastructure limits, identified bottlenecks, scaling recommendations, architectural observations, operational risks, and documented assumptions. The methodology explicitly recognises that these estimates are analytical forecasts derived from production behaviour and should complement comprehensive performance testing whenever such validation becomes operationally feasible.
5.Results
The assessment produced a comprehensive capacity profile for the production platform by independently evaluating every critical infrastructure component rather than relying on aggregate cluster utilization. Capacity estimates were generated for compute resources, container workloads, API gateways, database services, caching layers, storage systems, and supporting Azure platform services, allowing infrastructure bottlenecks to be identified before they became operational constraints.
The methodology provided engineering teams with quantified infrastructure headroom, projected resource exhaustion points, and component-specific scaling recommendations, enabling informed capacity planning based on observed production behaviour rather than theoretical infrastructure specifications alone. In addition to forecasting future resource requirements, the assessment documented assumptions, confidence levels, operational risks, and dependencies that could influence scaling behaviour, ensuring that infrastructure decisions were supported by transparent engineering analysis.
Although the methodology does not replace comprehensive end-to-end load testing, it demonstrated that production telemetry combined with structured engineering analysis can provide reliable capacity estimates in environments where traditional performance testing is impractical. The approach has been successfully applied across multiple enterprise production deployments over several years, supporting infrastructure planning while reducing both operational risk and unnecessary resource overprovisioning.
6.Learnings
Conducting this assessment significantly strengthened my understanding of Platform Engineering, Systems Architecture, and Infrastructure Capacity Planning by shifting the focus from deploying infrastructure to evaluating how production systems behave under real workloads. The project reinforced the importance of making infrastructure decisions using production telemetry, engineering analysis, and architectural constraints rather than assumptions alone.
A key takeaway was recognizing that platform scalability is determined by the interaction of multiple infrastructure components rather than a single service. Evaluating Kubernetes, Azure Application Gateway, API Management, MySQL, Redis, storage services, and networking as an interconnected platform highlighted the importance of identifying the true bottleneck before recommending scaling strategies.
The project also deepened my understanding of analytical capacity planning by developing structured methodologies to estimate future infrastructure requirements from observed production metrics. Documenting assumptions, limitations, confidence levels, and operational risks reinforced that engineering recommendations should be transparent, evidence-based, and clearly distinguish measured data from theoretical projections.
Most importantly, this work strengthened my systems thinking by emphasizing that effective platform engineering extends beyond infrastructure provisioning. It involves understanding service dependencies, forecasting growth, evaluating architectural trade-offs, and designing scalable, resilient environments that enable informed operational decisions while balancing performance, cost, and reliability.