Lightweight File Integrity Monitoring & Incident Response Tool
File Integrity Monitoring (FIM) solutions provide strong protection against unauthorized application changes but can be difficult to justify for organizations operating legacy platforms or cost-sensitive environments. This project delivers a lightweight Linux-based File Integrity Monitoring tool that continuously monitors critical application directories, detects filesystem changes in real time, generates operational alerts, automatically quarantines suspicious files, and self-recovers failed monitoring processes. The solution also includes automated environment provisioning and a standardized deployment procedure, enabling repeatable production deployments with minimal operational overhead. Designed for Linux-hosted applications, the tool provides an economical alternative for organizations seeking improved operational visibility and basic incident response capabilities without investing in commercial endpoint or file integrity monitoring platforms. This makes it particularly suitable for legacy application environments where budget constraints or infrastructure limitations prevent the adoption of enterprise security products.
Linux · Bash · Python
1.Overview
Background
A while back, I was dealing with an old Linux app at work that had a bad habit of getting files dropped into its directories that shouldn't have been there sometimes a bad deploy, sometimes just someone editing something live they shouldn't have. There was no real visibility into it. No commercial FIM tool made sense for something this old and low-priority; nobody was going to sign off on that budget for a legacy box.
So on my own time, I started poking around with inotify to see if I could build something simple that just watched the directories that mattered and told me when something changed. It wasn't a work assignment. I just wanted to know what was happening on that filesystem without babysitting it.
What I wanted it to do
Nothing fancy. Just:
- Watch a handful of directories continuously
- Tell me (by email, since that's what we already had) when something got created, changed, moved, or deleted
- Automatically pull suspicious files (specific extensions like
.jsp,.jar,.class,.py) out of the directory before they could do anything - Not die silently; if the watcher process crashed, something needed to notice and restart it
- Be something I could install the same way twice, not a one-off hack I'd forget how I set up
Solution Overview
The implemented solution consists of three cooperating operational components:
Component: Responsibility
Environment Setup Tool: Provisions the monitoring user, configures filesystem permissions, prepares the runtime environment, and applies required inotify kernel parameters.
File Monitoring Engine: Continuously monitors configured application directories, detects filesystem events, generates alerts, records audit logs, and quarantines files matching predefined conditions.
Process Watchdog: Continuously validates the monitoring engine and its dependent inotifywait processes, automatically restarting them if they terminate unexpectedly to maintain continuous protection.
Together, these components provide a lightweight monitoring capability that improves operational visibility while reducing manual intervention and deployment complexity.
Engineering Objectives
The solution was designed with the following operational objectives:
- Lightweight deployment using native Linux capabilities.
- Minimal infrastructure and software dependencies.
- Continuous monitoring of designated application directories.
- Automated alert generation and audit logging.
- Controlled quarantine of selected application artifacts.
- Self-healing monitoring processes to improve operational reliability.
- Standardized installation, verification, and rollback procedures for production deployments.
2.Gallery
Pinch or scroll to zoom (50%–800%) · drag when zoomed in
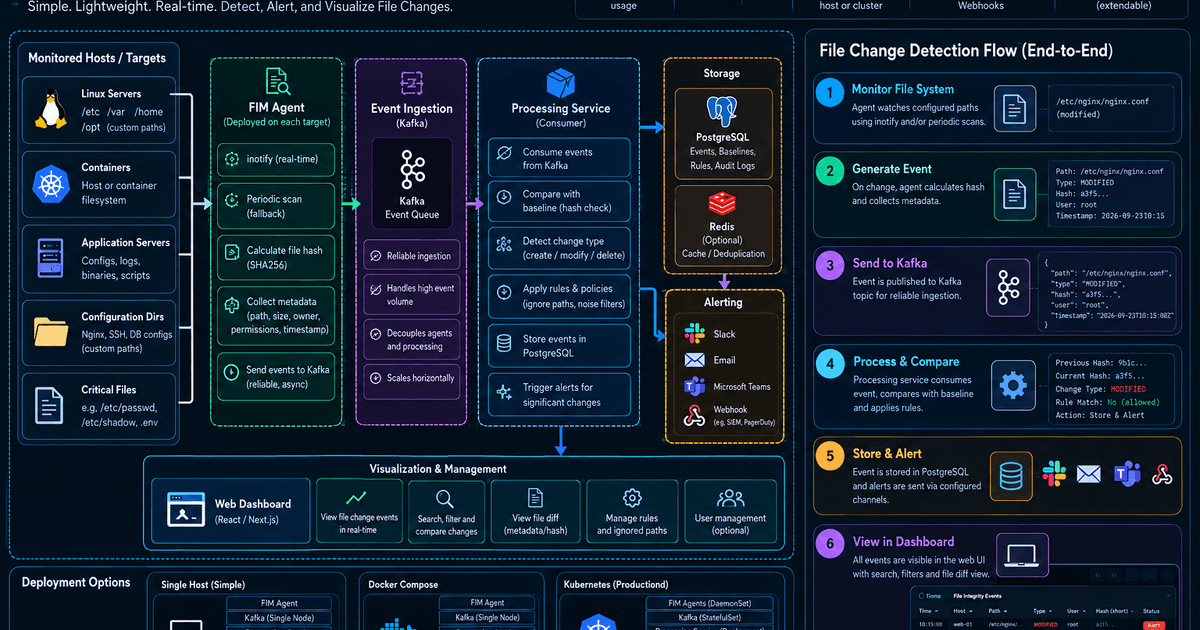
Pinch or scroll to zoom (50%–800%) · drag when zoomed in
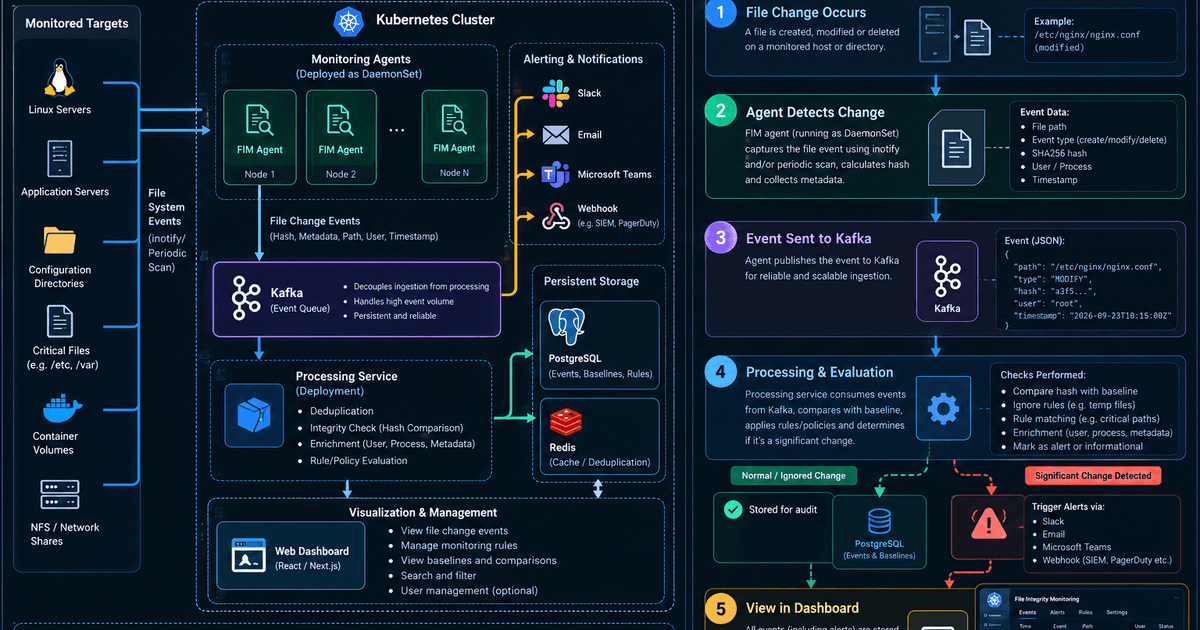
3.Architecture
flowchart LR

%% ============================================================
%% ENVIRONMENT SETUP
%% ============================================================

subgraph SETUP["Environment Provisioning"]
direction TB

A1["setup_script.sh"]

A2["Create Monitoring User"]

A3["Configure Group Membership"]

A4["Configure Filesystem Permissions"]

A5["Create Runtime Directories"]

A6["Initialize Log & Quarantine Directories"]

A7["Tune Kernel Parameters<br/>fs.inotify.max_user_watches<br/>fs.inotify.max_user_instances"]

A8["Deploy Monitoring Scripts"]

A1 --> A2
A2 --> A3
A3 --> A4
A4 --> A5
A5 --> A6
A6 --> A7
A7 --> A8

end

%% ============================================================
%% SERVER
%% ============================================================

subgraph SERVER["Linux Application Server"]

direction TB

subgraph MONITOR["Monitoring Services"]

direction LR

FM["file_monitorv2.sh"]

DP["double_pointer.sh<br/>(Watchdog Supervisor)"]

end

subgraph WATCHERS["Filesystem Watchers"]

direction TB

IW1["inotifywait<br/>Directory A"]

IW2["inotifywait<br/>Directory B"]

IW3["inotifywait<br/>Directory C"]

end

subgraph DIRECTORIES["Application Directories"]

direction TB

DIR1["Application Directory A"]

DIR2["Application Directory B"]

DIR3["Application Directory C"]

end

subgraph PROCESSING["Event Processing Pipeline"]

direction TB

P1["Receive Filesystem Event"]

P2["Normalize Event"]

P3["Duplicate Detection"]

P4["Write Audit Log"]

P5["Generate Email Notification"]

P6["Evaluate Quarantine Rules"]

end

subgraph QUARANTINE["Automated Response"]

direction TB

Q1["Validate Event"]

Q2["Check File Extension"]

Q3["Retry if File Locked"]

Q4["Move File to Quarantine"]

Q5["Log Quarantine Result"]

end

subgraph STORAGE["Operational Artifacts"]

direction TB

LOG["Audit Logs"]

QDIR["Quarantine Directory"]

end

end

%% ============================================================
%% OPERATIONS
%% ============================================================

subgraph OPS["Operations"]

direction TB

MAIL["Email Alerts"]

ADMIN["Operations Team"]

MAIL --> ADMIN

end

%% ============================================================
%% PROCESS SUPERVISION
%% ============================================================

subgraph HEALTH["Health Monitoring"]

direction TB

H1["Verify file_monitor Process"]

H2["Verify All inotifywait Processes"]

H3["Detect Failed Watchers"]

H4["Restart Monitoring Service"]

H5["Log Recovery Event"]

H6["Send Recovery Notification"]

end

%% ============================================================
%% FLOWS
%% ============================================================

A8 --> FM
A8 --> DP

DIR1 --> IW1
DIR2 --> IW2
DIR3 --> IW3

IW1 --> FM
IW2 --> FM
IW3 --> FM

FM --> P1

P1 --> P2
P2 --> P3
P3 --> P4
P4 --> P5
P5 --> MAIL

P3 --> P6

P6 --> Q1

Q1 --> Q2

Q2 -->|Supported Artifact| Q3
Q2 -->|Ignored| FM

Q3 --> Q4
Q4 --> Q5

Q5 --> QDIR
Q5 --> LOG

P4 --> LOG

DP --> H1

H1 --> H2

H2 --> H3

H3 -->|Healthy| FM

H3 -->|Failure Detected| H4

H4 --> FM

H4 --> IW1
H4 --> IW2
H4 --> IW3

H4 --> H5

H5 --> LOG

H5 --> H6

H6 --> MAIL

%% ============================================================
%% STYLES
%% ============================================================

classDef setup fill:#1f4b99,color:#fff,stroke:#0d2b5e;
classDef runtime fill:#2f6b3f,color:#fff,stroke:#174425;
classDef process fill:#7a5a00,color:#fff,stroke:#4d3600;
classDef security fill:#8b1e3f,color:#fff,stroke:#4a0d20;
classDef storage fill:#555,color:#fff;
classDef ops fill:#5a3e8c,color:#fff;

class A1,A2,A3,A4,A5,A6,A7,A8 setup;

class FM,DP,IW1,IW2,IW3,DIR1,DIR2,DIR3 runtime;

class P1,P2,P3,P4,P5,P6 process;

class Q1,Q2,Q3,Q4,Q5,H1,H2,H3,H4,H5,H6 security;

class LOG,QDIR storage;

class MAIL,ADMIN ops;4.Implementation
Phase 1 — Environment Provisioning
The monitoring environment is provisioned using a dedicated installation script responsible for preparing the operating system before runtime monitoring begins. The script creates an isolated monitoring account, configures filesystem permissions, prepares logging directories, and tunes kernel parameters to support a large number of filesystem watches.
One of the primary engineering considerations was avoiding manual post-installation configuration. Infrastructure prerequisites are therefore codified into a repeatable deployment script.
Creating the monitoring user:
monitor_user="monitor"

id -u "$monitor_user" &>/dev/null || useradd -m "$monitor_user"

monitor_password=$(openssl rand -base64 24)
printf '%s:%s\n' "$monitor_user" "$monitor_password" | chpasswd
unset monitor_password

usermod -aG application_group "$monitor_user"
This ensures deployments remain idempotent; existing users are reused while new environments are provisioned automatically.
Preparing the runtime environment:
touch "$log_file"

mkdir -p "/home/$monitor_user/scripts"

chown $monitor_user:$monitor_user "$log_file"

chmod 700 "/home/$monitor_user/scripts"
Separating runtime assets under a dedicated service account limits operational impact while simplifying ownership and log management.
Scaling inotify
Linux uses kernel limits to control the number of filesystem watches.
inotify_max_user_watches="1048576"
inotify_max_user_instances="1024"

sysctl -p
Increasing these limits enables the monitoring service to observe large application deployments without exhausting default kernel resources.
Phase 2 — Continuous Filesystem Monitoring
Once the operating environment has been prepared, the monitoring engine establishes persistent recursive watches on the configured application directories.
Rather than polling the filesystem at fixed intervals, the implementation uses Linux's native inotifywait utility to receive kernel-generated filesystem events. This event-driven architecture provides near real-time detection while consuming significantly fewer CPU resources than periodic scanning.
Each monitored directory is assigned an independent monitoring process, allowing filesystem events to be processed continuously without blocking other directories.
Establishing recursive monitoring
The monitoring engine establishes recursive filesystem watches across configured application directories.
inotifywait \
    -m \
    -r \
    -e modify,create,delete,attrib,move_self,moved_from,moved_to,close_write \
    --format '%e %w %f'
Several event types are monitored because no single filesystem event accurately represents every deployment scenario. File uploads, application deployments, modifications, permission changes, and file movements each generate different kernel notifications. Monitoring multiple event classes improves coverage while allowing later processing stages to distinguish between operational events and potentially suspicious behaviour.
Reducing operational noise
Production application directories generate a significant number of expected filesystem events. Monitoring every change would quickly overwhelm operators with unnecessary alerts.
To improve signal-to-noise ratio, the monitoring engine excludes known non-critical paths and file types.
--excludei '(.*/logs/.*|
             .*/cache_data/.*|
             .*\.(jpg|png|log|zip|gz|swp|swx|.*\~))'
Filtering transient files, caches, archives, logs, and temporary editor artifacts allows the monitoring service to focus on meaningful application changes rather than routine operational activity.
Phase 3 — Event Processing and Alerting
Every filesystem event captured by inotifywait enters a centralized processing pipeline responsible for enrichment, auditing, notification, and response.
Instead of immediately sending notifications, the monitoring engine first constructs a standardized event record containing the timestamp, event type, and affected file path.
event_info="Timestamp: $timestamp,
Event: $event,
File: $full_path"
Standardized event formatting simplifies log analysis while providing sufficient context for operational investigation.
Duplicate event suppression
Filesystem operations frequently generate multiple kernel events for a single user action.
To prevent excessive notifications, the implementation checks whether an identical event has already been recorded.
if ! grep -qF "$event_info" "$log_file"; thenSuppressing duplicate entries reduces alert fatigue while preserving the operational audit trail. This simple deduplication mechanism improves usability without introducing additional state management or databases.
Notification generation
Validated events trigger immediate operational notifications.
mail \
    -s "$email_subject" \
    -r "$email_sender" \
    $email_recipients
Using the native Linux mail subsystem avoids external dependencies while allowing integration with existing enterprise mail infrastructure. Simultaneously, all events are persisted to a timestamped operational log, ensuring notifications and audit records remain synchronized.
Phase 4 — Automated Quarantine
Detection alone does not prevent potentially unsafe application artifacts from remaining available within the deployment environment. The monitoring engine therefore includes an automated quarantine stage.
Rather than isolating every modified file, the implementation evaluates both the filesystem event type and the file extension before taking action.
if [[ "$event" == "MOVED_TO" ]]; then
    quarantine_file "$file_path"

elif [[ "$event" == "CLOSE_WRITE,CLOSE" ]]; then
Different filesystem events indicate different stages of file creation. Treating these separately reduces the likelihood of quarantining partially written files.
File type evaluation
Only application artifacts considered capable of affecting runtime behaviour are automatically quarantined.
if [[ "$extension" == "jsp" ||
      "$extension" == "jar" ||
      "$extension" == "class" ||
      "$extension" == "py" ]]; then

    move_file_in_background "$file_path"
fi
Restricting quarantine to executable or deployable artifacts minimizes operational disruption while focusing automated response on files most likely to influence application execution.
Reliable quarantine execution
Immediately moving a newly written file may fail if another process still holds an active file handle.
To address this, the implementation retries quarantine several times before declaring failure.
while [ $count -lt $retries ]; do
    sleep 1
    quarantine_file "$file_path"
done
Introducing retry logic improves reliability during deployments and reduces false failures caused by transient filesystem locks.
Phase 5 — Self-Healing Process Supervision
Continuous monitoring loses its value if the monitoring process itself terminates unexpectedly. To eliminate this operational risk, the solution introduces a dedicated watchdog process.
The watchdog continuously validates both the monitoring script and every associated inotifywait process.
if ! pgrep -f "$monitor_script" > /dev/nullIn addition to monitoring the primary process, the watchdog verifies that every configured directory still has an active filesystem watcher. This prevents partial failures where the monitoring script remains running but one or more directories are no longer protected.
Automated recovery
When a failure is detected, the watchdog performs a controlled recovery procedure.
pkill -f "$monitor_script"

pkill -f "inotifywait"

nohup "$monitor_script" > /dev/null 2>&1 &
The implementation deliberately terminates both the monitoring process and any orphaned watcher instances before restarting the monitoring engine. This guarantees that all recursive watches are recreated from a known-good state rather than attempting partial recovery.
Following recovery, the watchdog records the event and dispatches an operational notification, ensuring administrators remain informed while minimizing service interruption.
5.Results
The completed solution achieved its primary objective of delivering a lightweight, production-ready file integrity monitoring capability for Linux application environments using only native operating system utilities and minimal external dependencies. By combining automated environment provisioning, real-time filesystem monitoring, automated alerting, controlled file quarantine, and self-healing process supervision, the tool provides continuous operational visibility while remaining simple to deploy and maintain.
Unlike traditional monitoring scripts that terminate after detecting an event or require manual supervision, the implemented solution was engineered for continuous operation. The watchdog component continuously validates both the monitoring service and its underlying filesystem watcher processes, automatically restoring monitoring functionality whenever unexpected failures occur. This significantly improves operational resilience and reduces manual intervention during day-to-day operations.
The monitoring engine successfully captures a broad range of filesystem events—including file creation, modification, deletion, attribute changes, file movement, and completed write operations—while filtering common operational artifacts such as log files, cache directories, compressed archives, and temporary files. This selective monitoring approach reduces unnecessary alerts and allows operational teams to focus on events that are more likely to impact application behaviour.
A key outcome of the implementation is the introduction of automated containment. Instead of limiting the response to notification alone, the tool evaluates detected events against predefined operational criteria and automatically isolates selected executable or deployable application artifacts by moving them into a quarantine location. Retry logic is incorporated to accommodate transient filesystem locks during deployments, improving the reliability of containment without interrupting legitimate write operations.
Operational visibility was further improved through standardized audit logging and email-based notifications. Every validated event is recorded with contextual metadata, including timestamps and affected file paths, while duplicate event suppression minimizes alert fatigue by preventing repeated notifications for identical events. This provides operations teams with an auditable record of filesystem activity while ensuring alerts remain actionable rather than overwhelming.
From an operational perspective, the accompanying deployment procedure standardizes installation, validation, and rollback activities. It documents infrastructure preparation, monitoring deployment, verification, and operational testing, allowing the solution to deploy consistently across multiple Linux environments while reducing implementation variability.
The completed solution demonstrates that effective file integrity monitoring does not necessarily require a commercial security platform. By leveraging native Linux capabilities and a modular operational design, the tool delivers continuous monitoring, automated response, and self-healing behaviour while remaining lightweight enough for legacy or cost-sensitive application environments. The result is an operationally sustainable solution that enhances visibility, improves response time to filesystem changes, and reduces ongoing administrative overhead without introducing significant infrastructure complexity.
6.Learnings
This project reinforced several practical engineering principles beyond the implementation of a file monitoring utility. Developing a production-ready operational solution required balancing security, reliability, maintainability, and deployment simplicity while working within the constraints of existing Linux infrastructure and cost-sensitive environments.
1. Native Operating System Capabilities Can Deliver Effective Operational Solutions
One of the most significant takeaways was the effectiveness of leveraging native Linux capabilities instead of introducing additional software components.
The inotify subsystem provides near real-time filesystem event notifications directly from the Linux kernel, eliminating the need for periodic polling or heavyweight monitoring agents. Building the solution around native operating system features reduced resource consumption, simplified deployment, and minimized external dependencies while still providing comprehensive filesystem visibility.
Key takeaway
Existing operating system capabilities should be evaluated before introducing additional infrastructure or third-party software.
2. Detection Alone Provides Limited Operational Value
Early design considerations focused primarily on detecting filesystem changes. During implementation it became clear that detection without an operational response still required administrators to manually investigate and mitigate every event.
The final implementation therefore evolved beyond monitoring by incorporating:
Event validation
Automated notifications
Audit logging
Automated quarantine
This reduced the time between detection and initial containment while allowing operational teams to investigate suspicious changes without leaving potentially unsafe application artifacts within deployment directories.
Key takeaway
Monitoring systems should provide actionable responses rather than simply reporting events.
3. Reliability Must Include the Monitoring System Itself
A monitoring solution is only useful while it remains operational. During development, it became evident that unexpected process termination could leave application directories completely unprotected until manually restarted.
To address this, a dedicated watchdog service was implemented to continuously verify the health of both the monitoring process and its associated inotifywait instances, automatically restoring them whenever failures were detected.
Key takeaway
Production monitoring systems should monitor their own operational health, not just the target environment.
4. Reducing False Positives Is as Important as Detecting Events
Production application directories generate a large volume of expected filesystem activity. Monitoring every event without discrimination would overwhelm operators and reduce the practical value of the solution.
The implementation therefore excludes known operational artifacts—including log files, cache directories, archives, temporary files, and editor swap files—and suppresses duplicate event notifications before generating alerts. This significantly improves the signal-to-noise ratio and helps ensure that notifications remain meaningful.
Key takeaway
Effective monitoring depends not only on event detection but also on minimizing unnecessary operational noise.
5. Automation Improves Consistency Beyond Speed
Although manually configuring a monitoring environment is feasible, repeated deployments across multiple servers increase the likelihood of configuration drift and operational inconsistencies.
Automating environment preparation—including user provisioning, permission configuration, runtime directory creation, and kernel parameter tuning—ensured that deployments followed a consistent and repeatable process. Coupled with the documented procedures, this reduced dependency on manual installation activities and simplified operational handover.
Key takeaway
Infrastructure automation improves deployment consistency and operational reliability, not just deployment speed.
6. Operational Simplicity Encourages Adoption
Many organizations operating legacy or budget-constrained environments are unable to justify the licensing, infrastructure, or operational overhead associated with enterprise File Integrity Monitoring platforms.
By using native Linux utilities and a small set of cooperating scripts, the solution provides core monitoring, alerting, containment, and self-healing capabilities without requiring additional infrastructure or proprietary software. While it is not intended to replace comprehensive enterprise security platforms, it demonstrates that practical operational improvements can often be achieved through thoughtful engineering using existing platform capabilities.
Key takeaway
Lightweight solutions can provide significant operational value when they are designed around the constraints of the target environment.
Reflection
While the implementation intentionally remains lightweight, it highlights a broader engineering principle: effective operational tooling is not defined by its complexity but by its ability to solve a real operational problem reliably and consistently. By combining native Linux capabilities with modular design, automation, and operational resilience, the project demonstrates how practical engineering decisions can deliver meaningful value for legacy and cost-sensitive application environments without introducing unnecessary